Circuit Tracing in Vision–Language Models: Understanding the Internal Mechanisms of Multimodal Thinking
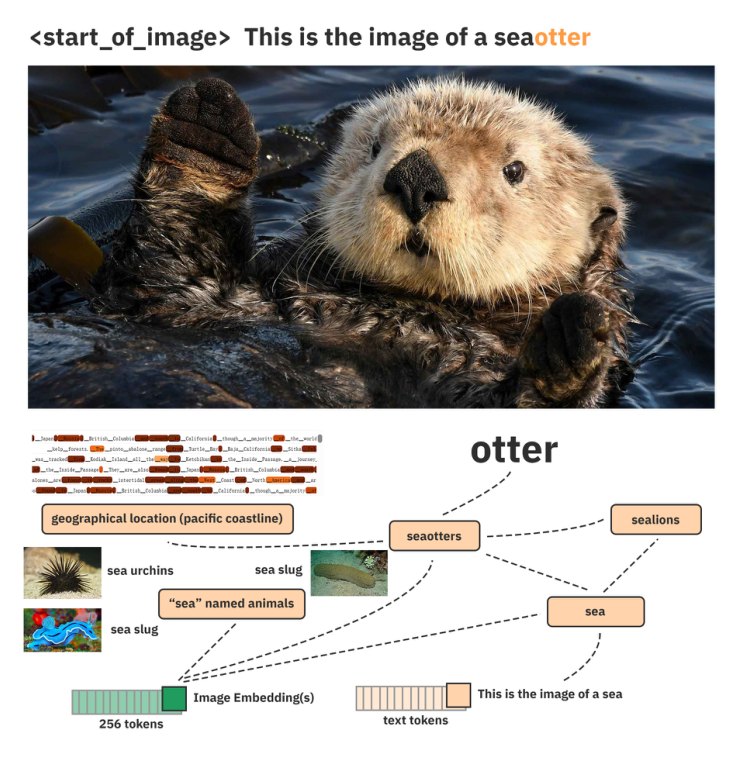
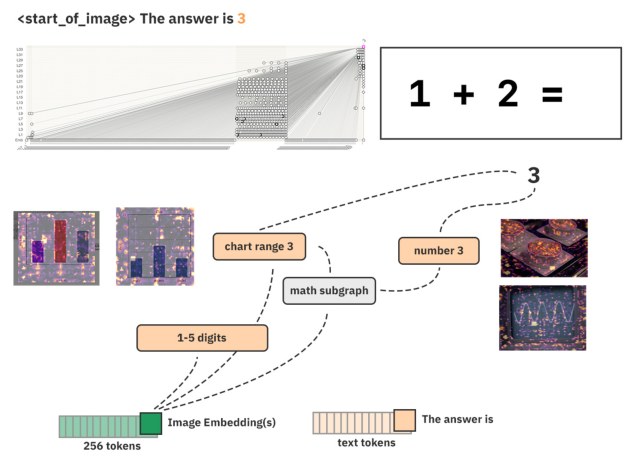
The first circuit-tracing framework for vision-language models. It shows which internal features Gemma-3-4B uses to reach an answer, and lets you turn those features up or down to test the explanation.
My contributions- Trained 34 per-layer TopK transcoders for Gemma-3-4B, one per MLP block. I extended EleutherAI Sparsify to Gemma-3's multimodal architecture and ran 30k steps on 8×H100 (about 60 hours) over a 360k-example text and image corpus.
- Built the feature-activation pipeline. I added vision-language hook points to TransformerLens at every MLP input and output, and computed activations on demand for only the features in each attribution graph (under 2,000 of 5.6M) instead of precomputing all of them, which cut compute and storage.
- Wrote the activation-patching and feature-steering modules that verify the circuits are causal and trace hallucinations down to individual features.